Key takeaways
- Azure Failure Prediction and Detection (AFPD) watches Azure’s servers for signs a part is about to fail, then moves your VM away before it crashes.
- Microsoft says it has cut hardware-related VM interruptions by about 36% and raised the monthly server repair rate by 80%.
- It runs automatically at no extra cost, but you only benefit fully if your apps listen for its alerts.
Azure now tries to spot a failing server before it takes your virtual machine down with it. In a Microsoft Azure Blog post, Azure CTO Mark Russinovich explains how a system called AFPD predicts hardware trouble and quietly works around it.
AFPD has been fully running across Azure since 2024. What’s new in this post is the real-world proof, using SAP customers as the example, and a clear list of things admins should switch on to get the most from it.
How AFPD works in three steps
Normally, a cloud hardware failure goes like this: a part wears out, your VM stops, an engineer investigates, and you wait for a reboot or a repair. AFPD tries to break that chain early.
1. Predict and detect
Machine learning models and detection rules scan health data from across the Azure fleet, including drive (SSD) health signals, looking for patterns that point to a failure now or soon.
2. Mitigate
A flagged server stops taking new VMs. Where it can, Azure live-migrates running VMs to a healthy server with no reboot, usually just a pause of a few seconds.
3. Remediate
The server is pulled out, tagged with diagnostic notes so technicians skip repeat checks, fixed with spare parts that are already waiting, and put back into service.
Live migration is not available for every VM. Microsoft says it works on many, but not all, M-series sizes (large-memory VMs often used for SAP). If your VM can’t be moved live, Azure posts a notice with a redeploy deadline so you can move it on your own schedule.
In their words
“Your first signal of a problem is often a notification that it’s already been handled.”
Mark Russinovich, CTO, Microsoft Azure, on the Microsoft Azure Blog
The results Microsoft reports
| Measure | What Microsoft reports |
|---|---|
| Hardware-related VM interruptions | About 36% better prevention across the fleet, and more than 36% fewer hardware reboots overall |
| Monthly server repair rate | Up 80% |
| Typical live migration impact | A pause of a few seconds, no reboot |
| Recognition | Best Paper Award, 2025 IEEE Cloud Summit |
| Cost to customers | None. It runs automatically, not as a paid tier |
These are Microsoft’s own fleet-wide figures, backed by its IEEE research paper. Your own results depend on your VM sizes and how many hardware events your servers happen to hit.
Why SAP is the example, and why it’s not just SAP
SAP systems often run a company’s finance, supply chain and operations, so even a short outage hurts. That makes them the clearest test case for AFPD.
Microsoft also admits a gap: many SAP customers don’t know the alerts exist, so they miss the chance to automate their response. AFPD itself covers far more than SAP. It runs across Azure’s General Purpose and Specialized Compute VMs, HPC and AI workloads, and some Storage scenarios.
Where AFPD alerts show up
AFPD sends the same alert content to several places. Pick the one that fits how you work.
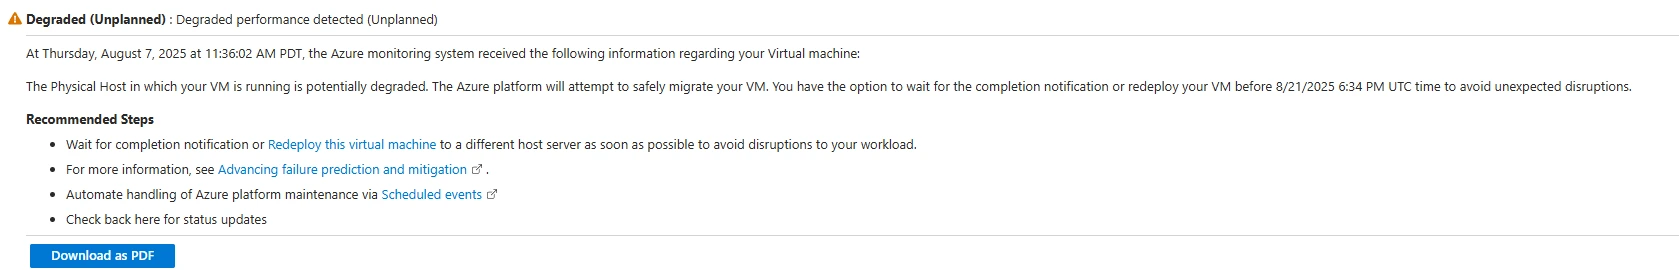
| Channel | Best for |
|---|---|
| Resource Health | Checking one VM: what happened, why, and what to do next |
| Resource Graph | Finding every affected VM across many subscriptions with one query |
| Event Grid | Automation: pushes alerts to a webhook, Azure Functions, Logic Apps or Azure Monitor without polling |
| Scheduled Events | Warnings from inside the VM, so clusters can move work off a bad server in time |
What Azure admins should do now
Quick checklist
- Pick an alert channel: make sure someone, or something, is reading AFPD notices through one of the four channels above.
- Handle Scheduled Events: your automation should cope with events whose start time (NotBefore) can be up to seven days ahead.
- SAP high availability: configure the Pacemaker azure-events-az resource agent using Microsoft’s guides for SUSE or RHEL.
- Check live migration support: look up your VM size in the M-family size tables before you count on no-reboot moves.
AFPD doesn’t replace good design. Zone-redundant setups, backups and failover plans still matter. What it does is make fewer of those plans necessary on an ordinary day, as long as your team hears the warnings.
Source: Microsoft Azure Blog
Discover more from Windows Mode
Subscribe to get the latest posts sent to your email.





Add your first comment to this post